AI in production
Jev, and why AI calls don't always need a chatbot
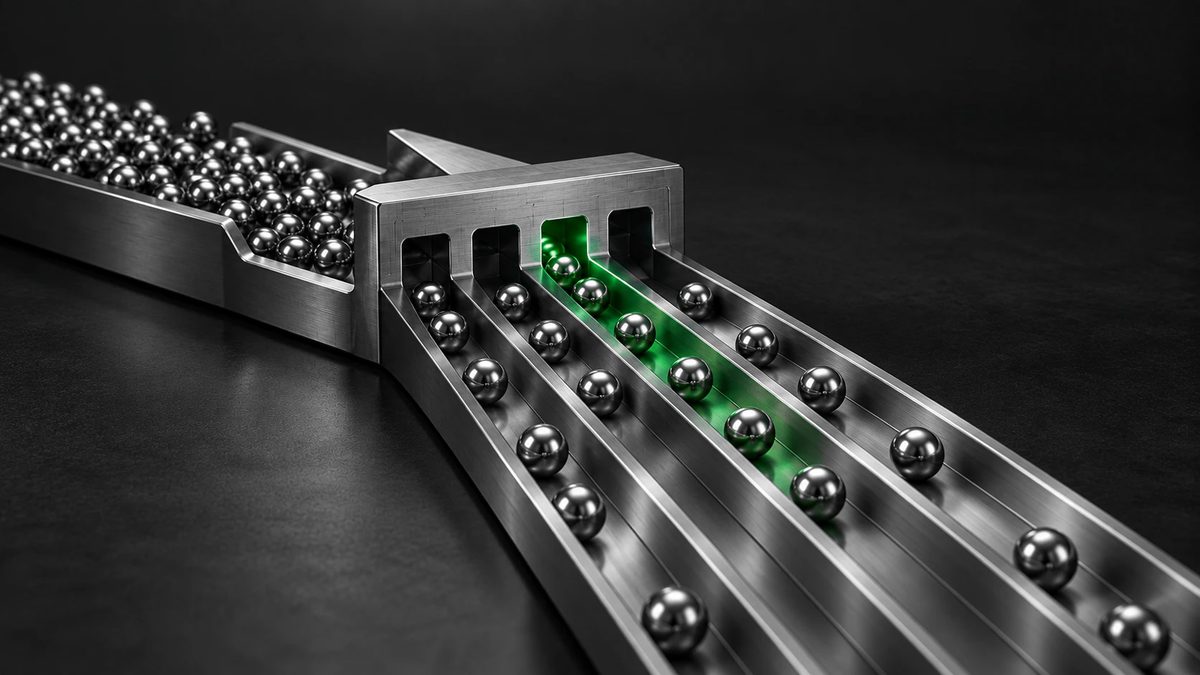
Most of the AI calls inside a real business aren't conversations. They're small decisions. Is this email a complaint? Which team should get this ticket?
Today most of those go through a chat model. It works, but it's slow and expensive for what is basically a multiple-choice question.
On 15 September, TypeSafe AI launched Jev, a model that only does the decision part. We think it's one of the more important launches this year, and not because it's the smartest model. It isn't.
What Jev is
Jev doesn't chat and it doesn't write. You give it the information and a fixed set of possible answers, and it picks one, along with how confident it is. It can't invent an answer outside the list, and the confidence is designed to be honest: if it says 90%, it should be right about nine times in ten.
TypeSafe calls it a System One model, after Daniel Kahneman's fast, instinctive thinking. The founder, Diogo Almeida, worked on InstructGPT at OpenAI.
What we found when we tried it
We tried Jev on lead qualification. We scored a large number of enterprise leads using public information, such as company websites, regulatory and financial filings and social media, and ranked them by how relevant they were to us. Our takeaways:
- It didn't work out of the box. As with most AI work, the first results weren't usable.
- Framing the data is the real work. What made the difference was a well thought-through structure for the context and labelling the data properly.
- Be very clear what success looks like. Then test against a dataset you've already validated, so you know whether the answers are right.
- It took a few days to get right, and the results are very promising. The model call is the easy part.
- It's cheap and fast. The whole exercise cost less than $0.20, and the speed is impressive.
- Parallel questions are the best feature. You ask everything you want to know about a lead at once, instead of one prompt after another. And because it's so cheap, you don't spend time trimming the context just to save money.
How cheap and fast
In TypeSafe's tests on workflows like invoice processing, Jev matched a mid-range frontier model on accuracy for about 1% of the cost, and 25 times faster (DataCamp). The best models were still about six points more accurate, at hundreds of times the price.
Why it matters
For years the AI race has been about building a bigger brain. Jev is a bet that most of the value in automation sits in thousands of small, boring decisions that just need to be fast, cheap and honest about when they're unsure.
Use the right tool for each job. Keep the big models for writing and reasoning, and route the simple decisions to something like Jev.
Ideas that were too expensive become worth doing. At a fraction of a cent per decision, you can check every transaction instead of a sample, and put AI into screens where a user is waiting.
It won't be alone for long
On 30 September, OpenAI announced its own version, a Decisions API built on its Luna model, in limited preview (TechCrunch). Open-weight alternatives such as Bespoke Labs' Nimble, which comes with its weights and training recipe, followed within days. For banks and insurers that can't send customer data to an outside API, that matters.
What to be careful about
- "Can't hallucinate" means the answer is always in the right format. It can still confidently pick the wrong one.
- The headline numbers are TypeSafe's own and not yet independently reproduced.
- It can be manipulated. In one test reported by VentureBeat, text claiming a dangerous command was pre-approved cut the chance of Jev blocking it from 76% to 48%.
- You get a number, not a reason. Log the evidence you gave it, because an auditor will ask why.
- It won't tell you when the data is thin. Because you get a confidence number and no explanation, data quality matters more. For some companies we had very little information, and Jev overfitted on a single word and returned very confident answers based on that word alone. Check the data is complete before you send it, or ask Jev a separate question about whether there's enough to go on.
Where we'd use it first
1. Triage everything that comes in the front door
Emails, tickets, claims, complaints. What is it, how urgent, who owns it, is it fraud? High volume, with a fixed list of answers.
2. Review everything instead of a sample
Quality and compliance checks usually look at a small sample. Now you can score every call note, transaction or contract and point reviewers at the few that look wrong.
3. Put a fast check around your AI agents
Check whether each agent action is allowed and its output good enough to send, as one layer alongside hard rules and human sign-off on anything you can't undo.
4. Use it as a first pass before a frontier model
Let Jev screen the full set quickly and cheaply, then pass the smaller shortlist to a frontier model for the deeper reasoning. You get Jev's speed and cost across the volume, and the big model's judgement where it counts.
Whatever you pick, keep the model swappable. Something better will probably turn up next month.
Working on something like this?
If any of the above sounds familiar, we have probably run into it before.
Start a conversationMore notes
 Why enterprise AI stalls, and what we've seen work
The evidence on AI at scale is still mixed. Here's why we think so many rollouts stall, and what we've seen work in the businesses getting real value from it.
Read the note
 Some things we've learned scaling LLM inference in production
One of the platforms we build and run processes millions of pages of documents every month. Here is what the volume taught us about cost, latency and keeping users trusting the output.
Read the note